Endpoint management is the operational discipline of governing enterprise devices across their entire lifespan, from the moment hardware is received through provisioning, active use, and eventual cryptographic decommissioning.
A June 2025 Enterprise Strategy Group survey of IT and cybersecurity professionals found that 59% of unmanaged endpoints are unintentionally unmanaged, meaning they fell out of a management workflow rather than being excluded on purpose. That gap is almost always a lifecycle handoff that never got built, and it’s a direct driver of workforce productivity loss and support costs.
Most guides treat that problem as a procurement exercise. They define what an endpoint is, describe enrollment steps, and stop there. For IT managers and senior engineers running mixed fleets across Windows, Linux, and Android, the harder question is operational: how does a hardware signal become a remediation action before the affected employee notices anything is wrong?
This guide answers that question through a seven-stage framework covering Discover, Enroll, Configure, Maintain, Monitor, Support, and Retire. Each stage maps to a specific authority domain and a specific set of tools. The section on Monitor and Support describes the feedback loop that separates teams running proactive fleets from those perpetually triaging tickets.
What counts as an endpoint today
An endpoint is any device that connects to the corporate environment, runs managed software, and carries organizational data. For most enterprise fleets, that means Windows workstations and laptops, Linux developer machines and thin clients, Android devices used in field or retail roles, and the growing range of commercial-grade PCs that straddle multiple form factors.
Managing an endpoint means governing its full runtime state and complete ownership record, not just confirming enrollment. A device can pass every MDM compliance check and still run a months-old BIOS build with an unpatched firmware vulnerability, or appear healthy in your asset database while its SSD wears out. Both failures reflect incomplete endpoint management and can lead to a user-filed incident that could have been prevented.
Runtime state covers everything actively affecting the device’s behavior, including OS version, driver set, firmware revision, patch status, application crash frequency, battery charge capacity, and storage wear. The ownership record covers the administrative chain, including the assigned user, the cost center that owns the asset, the warranty expiration date, and the decommissioning timeline. A mature endpoint management practice keeps both dimensions current, not just the enrollment status.
Modern unified endpoint management (UEM) extends this governance across heterogeneous operating systems under a single policy and telemetry layer. An IT team using UEM can push a firmware policy to a fleet of HP EliteBooks running Windows, apply configuration baselines to Linux workstations, and monitor Android device health from the same console, without separate toolchains for each OS.
The seven stages of endpoint management as a lifecycle framework
The device lifecycle runs through seven distinct stages, and the most common mistake in fleet management is treating them as a one-way conveyor belt. Provisioning happens, the device ships to a user, and then everyone waits for something to break. The resulting posture is largely reactive. A more accurate mental model is a loop. Monitor and Support feed directly back into Maintain, closing a continuous operational cycle rather than sitting at the end of a chain.
The seven stages and their four authority domain handoffs are mapped in the flowchart below.
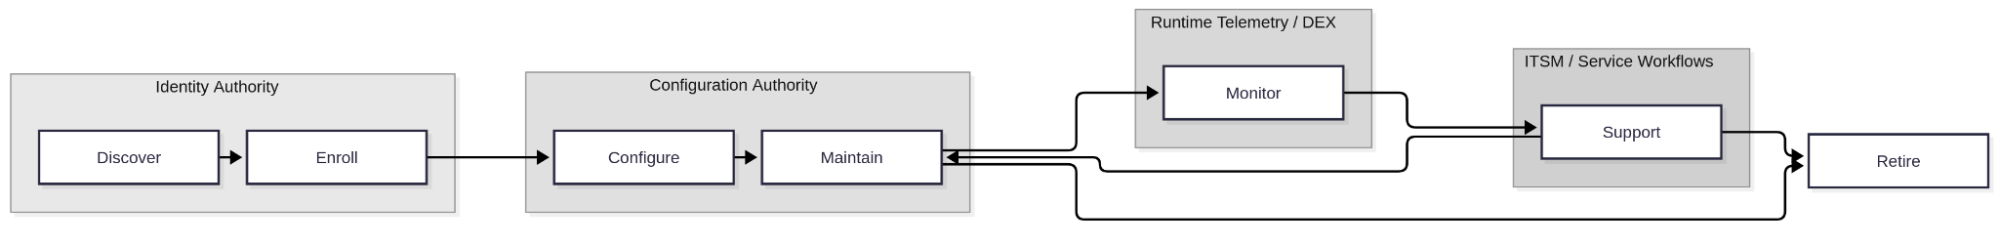
The seven-stage endpoint management lifecycle as a loop
Four authority domains govern the lifecycle. The Identity Authority (your directory and MDM enrollment layer) owns Discover and Enroll. The Configuration Authority (your policy and patch toolchain) owns Configure and Maintain. Runtime Telemetry and the Digital Employee Experience (DEX) layer own Monitor. ITSM and service workflows own Support.
Handoffs between domains are where incidents fall through. A device that enrolls in MDM but never enters the Configuration Authority’s scope runs without a managed policy baseline. A device that Monitor flags for a failing SSD but has no automated handoff to Support often ends up generating a user-filed ticket anyway. Identifying and closing those handoff deltas is the core operational challenge of fleet management.
Discover, enroll, and configure
The provisioning arc spans three stages, and each has a specific authority handoff that must complete cleanly for the remaining stages to work.
Discover starts at procurement. When a device ships, you can register its hardware hash (a cryptographic fingerprint derived from hardware identifiers) directly in your tenant before the device ever leaves the box. That hash then appears in your configuration management database (CMDB) as a known asset, giving the identity layer a record to match against when the device first connects. For Windows devices, this registration feeds into Windows Autopilot, Microsoft’s zero-touch deployment service, which uses the hash to associate the device with your tenant and apply the correct Autopilot profile automatically.
Enroll turns a known asset into a managed one. Zero-touch enrollment paths handle this without user intervention. For Autopilot-registered devices, the out-of-box experience completes, the device calls home to your tenant, and the Autopilot profile applies the correct MDM enrollment. For organizations managing fleet telemetry through a platform like HP Workforce Experience Platform (WXP), for example, the WXP Insights Agent deploys alongside MDM enrollment through one of a few paths: as a Win32 app via Microsoft Intune, through SCCM, or through Group Policy with a preconfigured startup script. Using one of these scripted or silent methods, rather than an interactive manual install, generally avoids prompting the end user during setup.
Verifying that enrollment completed correctly is essential at this stage. In the WXP portal, go to the device inventory view to confirm the newly enrolled endpoint appears with active telemetry. If an endpoint fails to check in, a utility like the WXP Insights Health Checker can run local self-diagnostics covering connectivity, proxy configuration, and service status, producing a diagnostic log that points to the root cause.
Configure is where policy meets device reality. Two configuration levers typically operate in parallel: BIOS and firmware policy, and OS-level policy. BIOS and firmware policy needs a tool that can push enterprise settings and update packages as managed policies without someone physically touching each machine; HP Connect for Intune, for example, pushes those policies through Intune for HP devices. OS-level configuration is what lets policy scale across a fleet, and group-based rules are generally how that works: devices get grouped automatically by inventory attributes like manufacturer, model, operating system, or serial number, and any policy assigned to that group applies to every matching device from then on. In WXP, for example, that’s the Groups module’s Dynamic Rule groups — a group defined as “HP EliteBook, Windows 11, Finance department” automatically captures every device matching those criteria, and a policy assigned to that group typically reaches those devices within about 15 minutes of the next agent sync.
Configuration scale becomes a function of rule design rather than manual assignment this way. When a new device enrolls and matches an existing rule’s criteria, it automatically inherits the full policy baseline for that group, with no administrator action required after the initial group setup.
Maintain and monitor
Maintain and Monitor are the two stages where proactive fleet management either takes hold or breaks down. Maintain keeps enrolled, configured devices in their intended state. Monitor surfaces hardware signals that show a device is drifting before the user notices.
Maintain covers three categories of ongoing work:
- Patch hygiene means something more specific than running Windows Update. At the fleet level, it means managing update rings that control which devices receive updates first, validating that pilots succeed before broader rollout, and confirming that patches have actually applied rather than just been offered.
- Driver and firmware updates follow the same ring model. A tool like HP Connect for Intune can manage BIOS and firmware update policies, staging a firmware revision to a test group, validating it, and then promoting it to the broader fleet.
- Drift detection, the part that many patch management tools handle poorly: a device can receive a policy, acknowledge it, and then revert due to a local change, a conflicting application, or a failed update. Endpoint management software that flags endpoints whose actual state deviates from their assigned policy baseline, without waiting for a full vulnerability scan cycle, is what closes that gap.
Monitor is where the feedback loop that defines proactive fleet management actually operates: surfacing failure signatures before the affected user experiences any degradation, rather than waiting for a ticket. For example, on HP hardware enrolled in WXP, Predictive Hardware Health collects low-level sensor telemetry and runs it through ML-driven analysis to achieve that.
For batteries, that typically means tracking full charge capacity against design capacity and accumulating charge cycle data over time. When capacity drops below a serviceable threshold, the platform can alert the user and trigger a replacement workflow before unexpected shutdowns occur.
For solid-state drives, this means monitoring S.M.A.R.T. telemetry, such as total bytes written against vendor endurance ratings and spare block exhaustion, as the drive consumes its reserved pool. An SSD approaching end-of-life often shows signals before it fails: wear indicators trend upward and spare block counts trend down, which a device health dashboard can surface well before failure.
For system stability, aggregating BSOD telemetry by stop code and faulting driver lets you distinguish an isolated hardware defect on a single machine from a fleet-wide regression caused by a bad driver update.
The monitoring signal reaching the ops team before the performance complaint reaches the service desk is what proactive fleet management looks like in operation.
Support and retire
Support and Retire close the lifecycle loop. Support converts monitoring alerts into targeted actions before users are affected, and Retire ensures devices leave organizational custody with a complete, audit-ready decommission record.
Support in a telemetry-driven fleet works differently from traditional break-fix models. A health alert for an SSD approaching failure can trigger a targeted action, whether that’s a proactive parts dispatch, a scheduled replacement appointment, or an automated remediation workflow, without waiting for the affected user to submit a ticket.
An API-first architecture is what makes automated ITSM handoffs possible at scale. A device health alert, generated for example by WXP’s Predictive Hardware Health engine, can post to a connected ITSM system such as ServiceNow through the WXP REST API, creating an incident record with the device and the failure signal attached before the user has noticed anything wrong. Running that kind of handoff without human intervention is generally what makes it possible to operate the feedback loop at real fleet scale.
For lost or stolen devices, a platform like WXP can surface controls such as HP Protect and Trace directly in the device record. IT administrators initiate a remote lock or erase from the device record; the request goes through a separation-of-duties approval step involving one or more designated approvers, and approvers authenticate through the HP Wolf Protect and Trace Approver App using PIN or Windows Hello. On Wolf Connect-enabled hardware, the erase command can be delivered out-of-band over a cellular connection, so the command can execute even when the device is powered off, disconnected from Wi-Fi, or running a damaged OS.
Retire closes the lifecycle loop, and it carries security and compliance obligations that informal asset write-offs miss entirely. The cryptographic steps are specific. On HP hardware, HP Secure Erase runs within the commercial UEFI/BIOS, performing hardware sanitization aligned with NIST SP 800-88 Rev. 1 at the Purge or Clear level. The erase sanitizes physical drive blocks and partition tables, affecting both the host OS and the encrypted volumes. In addition, a TPM clear invalidates the BitLocker PCR measurement registers and destroys the cryptographic keys stored in hardware, making the drive’s contents unrecoverable even if the physical media is removed and attached to another system.
After sanitization, the decommission sequence in a platform like WXP removes the device from the active fleet: locating the device record, confirming the removal, and transitioning it to an inactive or unenrolled state. Any cellular connectivity licenses return to the organization’s subscription pool, and the device record archives according to the tenant’s configured data retention period. Hardware hash deregistration from Autopilot follows, removing the device from the identity layer and completing the ownership transfer.
This retirement process produces an audit-ready trail covering the sanitization method, compliance level, approval chain, and decommission timestamp. An asset write-off without those steps produces a liability instead.
Mapping ownership and tooling across the endpoint management lifecycle
Each of the four authority domains governs specific lifecycle stages, and the handoffs between them are where operational deltas most often appear:
- Identity Authority (Active Directory, Entra ID, Windows Autopilot) governs Discover and Enroll. It holds the hardware hash registry, manages the enrollment profile assignment, and determines whether a device is a known, trusted asset before the Configuration Authority touches it.
- Configuration Authority (Intune, SCCM, HP Connect for Intune, and a platform’s remediation and group modules) governs Configure and Maintain. It holds the policy baseline, the firmware update rings, and the drift detection logic.
- Runtime Telemetry and DEX (a capability like WXP Predictive Hardware Health and its alerting layer) governs Monitor. It collects the hardware signals, runs the ML models, and generates the alerts that feed into Support.
- ITSM and Service Workflows (ServiceNow or equivalent, connected via a REST API) governs Support. It receives the automated handoffs, owns the incident and work order records, and closes the loop back to Maintain when a remediation action changes the device’s state.
A practical exercise for any ops team is to build a seven-stage matrix for your own stack. For each stage, record which tool owns it and which team holds authority over that tool. Then check whether Monitor and Support share a live telemetry feed. Where they don’t, where Monitor generates alerts that a human reads and then manually creates an ITSM ticket, the handoff is manual, and every device that fails during off-hours or between review cycles tends to generate a user-filed incident rather than a system-generated work order.
Any stage without an automated Monitor-to-Support handoff is a delta in the operational loop, and closing that delta is the concrete next step for any fleet that still runs primarily in reactive mode.
Frequently asked questions
What is endpoint management?
Endpoint management is the operational discipline of governing enterprise devices across their full lifespan, from procurement and hardware registration through active fleet operations to cryptographic decommissioning. It encompasses hardware inventory, OS and firmware policy enforcement, patch hygiene, runtime health monitoring, automated support workflows, and compliant device retirement. A mature endpoint management practice governs both each device’s runtime state (OS version, driver set, firmware revision, application stability) and its ownership record (assigned user, asset tag, warranty status, decommission timeline), keeping both dimensions current throughout the device’s operational life.
What is unified endpoint management (UEM)?
Unified endpoint management is the practice of governing a heterogeneous fleet of devices across Windows, Linux, and Android under a single policy and telemetry layer. A UEM approach replaces the parallel toolchains that historically managed each OS separately with a consolidated console where IT teams can define configuration baselines, enforce patch rings, monitor device health, and respond to incidents regardless of the underlying platform. The value is operational consistency: the same group-based policy assignment and telemetry feed cover every managed device, reducing the administrative overhead of maintaining separate workflows for each OS type.
What are the seven stages of the endpoint lifecycle?
The seven stages are Discover, Enroll, Configure, Maintain, Monitor, Support, and Retire. Discover covers hardware hash registration and CMDB handoff at procurement. Enroll turns a known asset into a managed one through zero-touch MDM enrollment and telemetry agent deployment. Configure enforces BIOS, firmware, and OS policy baselines through group-based assignment. Maintain covers patch hygiene, driver and firmware update rings, and policy drift detection. Monitor collects runtime telemetry and surfaces predictive hardware health signals before users are affected. Support converts monitoring alerts into targeted actions through automated ITSM workflows. Retire executes cryptographic sanitization, hardware hash deregistration, and e-waste compliance steps before the device leaves organizational custody.
What is the difference between endpoint management and mobile device management?
Mobile device management (MDM) is a protocol layer, specifically a set of enrollment and policy-enforcement APIs built into modern operating systems that let an MDM server push configuration profiles, enforce compliance rules, and trigger remote actions. Endpoint management is the broader operational discipline that uses MDM as one of several tools. A complete endpoint management practice also spans hardware-level firmware governance (which MDM protocols do not reach), application health monitoring, identity authority management, ITSM integration, and compliant decommissioning. MDM handles OS enrollment and policy enforcement, while endpoint management governs everything from the hardware sensor to the recycling certificate.
How does telemetry change how endpoint support works?
Telemetry shifts the trigger for support action from the user to the device. In a ticket-driven model, support begins when a user reports a problem, which means the failure has already affected productivity. In a telemetry-driven model, the device itself generates the signal. A battery capacity reading drops below a serviceable threshold, an SSD’s spare block count trends toward exhaustion, or a specific driver correlates with an elevated BSOD rate across a device model. Those signals can reach the ops team through automated alerts and post directly to ITSM as pre-populated work orders via API, often before the affected user notices any degradation. The practical result is that proactive dispatch, parts replacement, or automated remediation can complete before a ticket is ever filed.
What is the Monitor-to-Support handoff and how does it work?
The Monitor-to-Support handoff automatically connects a device health alert to an ITSM work order. When a predictive hardware health engine detects a failure signal, such as an SSD approaching wear limits or a battery dropping below a serviceable capacity threshold, it can post an incident record directly to a connected ITSM system like ServiceNow. In HP Workforce Experience™ Platform (WXP), for example, the WXP REST API, built on the platform’s Predictive Hardware Health capability, handles that. That automation means remediation can begin before the affected user files a ticket. Fleets without this handoff rely on a human to read the alert and manually create the work order, which introduces delay and creates coverage gaps during off-hours.
How do Dynamic Rule groups work in WXP?
Dynamic Rule groups in WXP automatically populate based on device inventory attributes such as manufacturer, model, operating system, or serial number. When a new device enrolls and matches a group’s criteria, it inherits the full policy baseline assigned to that group without administrator action. A group defined as “HP EliteBook, Windows 11, Finance department” automatically captures every matching device, and a policy assigned to that group typically reaches those devices within about 15 minutes of the next agent sync. Configuration scale becomes a function of rule design rather than manual assignment.
Final thoughts on endpoint management
The shift from a linear provisioning model to a continuous operational loop changes fleet management. Discover through Configure gets devices into a known-good state, while Maintain and Monitor keep them there and surface failures before users notice. Support and Retire close the loop at both ends, with automated ITSM handoffs on the proactive side and cryptographic decommissioning on the offboarding side.
Specialist guides in this cluster go deeper on each stage. The enrollment guide covers Autopilot registration and WXP Insights Agent deployment in detail, the configuration guide covers Dynamic Rule group design and HP Connect for Intune firmware policy management, and the monitoring guide covers WXP Predictive Hardware Health alert configuration and ITSM API integration.
Explore how WXP instruments the Monitor-to-Support feedback loop at workforceexperience.hp.com, or browse the developer API documentation at developers.workforceexperience.hp.com.